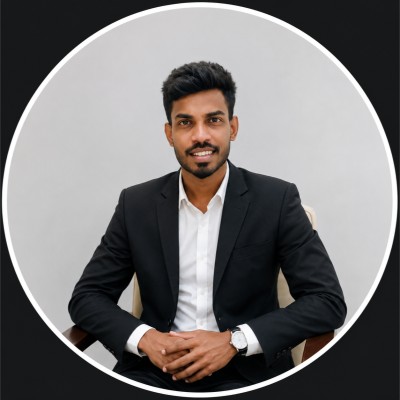
I'm Lahiru Niroshan Sathsara. I administered production Oracle databases for core banking, and I build data projects around reliability, clear pipelines and useful analytics. I'm looking for data engineering and data analytics roles.
Streaming, reconciliation, controls and analytics. The data is simulated; the engineering and measurements are real.
StreamingData engineeringIn development
F1 Real-Time Data Pipeline
An OpenF1-fed streaming architecture stores race data in PostgreSQL and processes Kafka events with Spark into Cassandra. Airflow orchestration is in progress; dashboards are planned.
4,119+ laps storedSpark → Cassandra completeAirflow in progress
Reconciles a simulated core-banking database against its reporting replica. Cheap partition checks run first, and row hashing only runs where drift is suspected.
100% precision and recall on injected faults6.4× at 1M rows13/13 tests
Grouped by the job they do. What I'm still learning is kept separate on purpose.
Store and protect
Where the data lives
OraclePostgreSQLSQLDuckDB
Move and transform
How it gets where it is going
PythonPandasKafka
Ship and show
How people see it
DockerStreamlitPower BIGit
Learning next
On the roadmap
AirflowSparkCassandradbt
What I can do
Where I add value.
Four things I can take on from day one, each backed by a project you can open.
⚙
Reliable pipelines
Ingest, store and process data with Kafka, Spark, PostgreSQL and Docker, built to run end to end.
See: F1 Real-Time Pipeline✓
Data quality and reconciliation
Find silent drift between systems, classify it, and leave evidence someone can act on.
See: DataGuard▦
Dashboards and reporting
Turn tables into decisions with Streamlit, Power BI and DuckDB, with metrics defined once.
See: Billing Assurance, Uber Eats🛡
Database administration
Oracle 19c/24ai on production servers: backup and restore with RMAN, query tuning, monitoring scripts.
Experience: VS Information Systems
How I work
Four habits from production.
Working on live banking databases taught me to trust data only after checking it.
1
Understand the source
Where the data comes from, who depends on it, and what a bad day looks like.
2
Validate early
Checks at each hop, so problems are caught where they start.
3
Build and automate
Containerised, repeatable, and easy to rerun after a failure.
4
Explain the result
Clear numbers, stated limits, and notes the next person can follow.
A little about me
From keeping databases running to building what runs on them.
I started in IT support, then administered production Oracle systems supporting core banking. That shaped how I build: check the data, understand what can fail, and make the results useful. My next step is data engineering, with analytics built on top.
 Oracle
 Python
 PostgreSQL
 Kafka
 Docker
 DuckDB
 Streamlit
 Pandas
 Power BI
 Spark
 SQL
 Git
 Airflow
 Cassandra
 dbt